Use the source, don't read it : ezyang's blog
20 Comments
- This is why we need literate programming. Write the source in book form. A table of contents, an introduction, chapter by chapter, and an index. Write to communicate ideas, structure from ideas to implementation. The book includes the actual source code. The net result is that code has fewer bugs (since the programmer has to review the code and the code review team has a clue about why the code was written) and the code will live longer because non-authors can understand and maintain it. The time has come for professional programmers to “raise their game” and write to communicate to humans as well as the machine.
Tim Daly
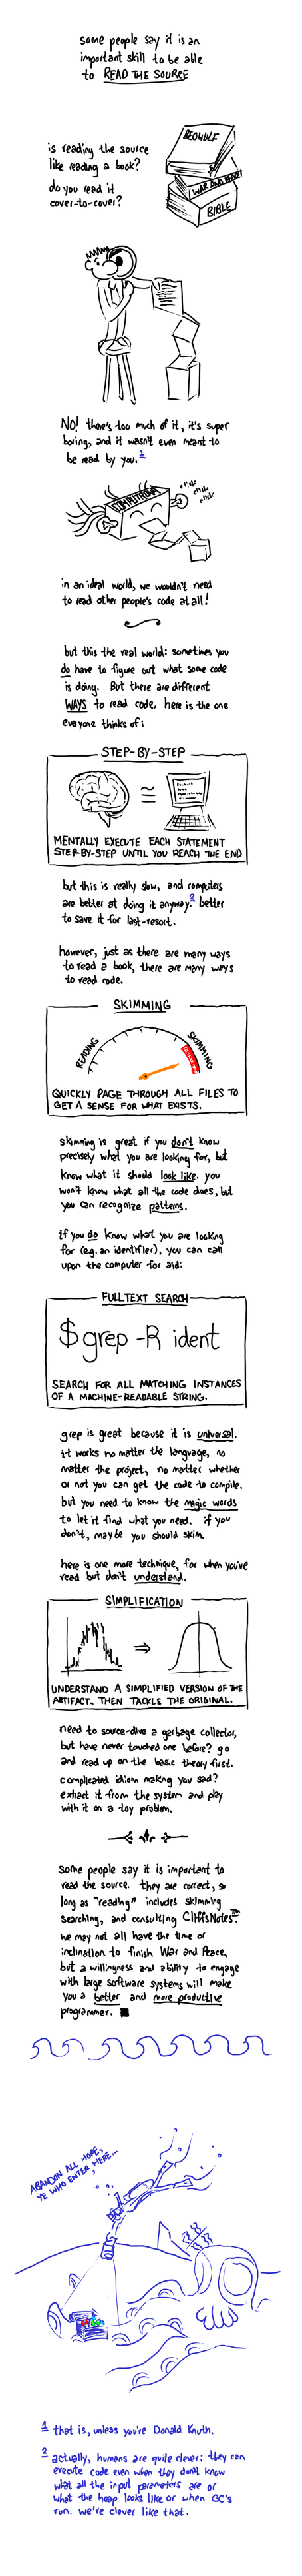
- I don’t get why you post text as image.
I really like your rants, but I prefer the text ones. They are easier to read, skim, etc.
Just like “Anonymous” said, the contents of this post is lost in the internet. No one searching for advice will find it, unless they can infer the content from the title and are willing to take a peek at the link. Grep, Google, Bing or whatever search engine is blind to this content.
Back to the matter;
Is this a response to Jeff Atwood’s recent post “Learn to Read the Source, Luke”?
I see you both defending the same point of view: you need to understand what you are using, even if it’s just the outline. As a problem appears, you should seek enlightment thru source code reading/skimming/browsing before shouting out your problem in StackOverflow with no real understanding of what’s going on.
Agreed.
- […] Use the source, don’t read it - Inside 233 has an excellent little (hand written/drawn) guide to how you should best make use of the source access that open source gives you, discussing a number of useful approaches to ‘reading’ and comprehending source code. […]
- @Bugger: This is the kind of One True Scotsman argument that gets bandied about anytime people talk about coding: “REAL CODE doesn’t have errors, is documented flawlessly, and cures world peace HURRRR”. The truth is, no interface/technical doc is 100% usable or reliable.
Also, what happens when you’re using a slightly different web browser/operating system patch level/cup stacker firmware than the software was written for, and it breaks? Is that “shitty code”? No. It’s just a fact of life that we’re trying to hit a moving target every time we sit down at an IDE (or vim, or notepad, or whatever). Calm down, Bugger, and try to take this post in the spirit it was intended.
- I agree, it’s important to examine the source, no necessarily read it. The first thing I do with source code is run it through applications like enterprise architect and visual studio’s auto-diagramming features.
I can’t say you shouldn’t evaluate code at all as some people do (hence, last project I found code that a contractor had written which was feeding business data to a free web service in inda he was using for processing). But I agree, it’s not necessary to intimately understand every line, just check for traps!
- The fastest method of understanding code isn’t mentioned here: use the debugger. Say you’re looking at a bit of code, but you don’t understand how a user interaction causes it to be called, or what the inputs are - just set a breakpoint, do the thing that gets it to be called and look at the call stack and any parameters. If the breakpoint isn’t hit, you might be looking at dead code, or just in the wrong place. Or if you’re just trying to understand an algorithm, don’t mentally execute it, step through it.
- Grep is universal? Maybe in unix.
- grep <<<< /?
- CategoryInfo : ObjectNotFound: (grep:String) [], CommandNotFoundException
- FullyQualifiedErrorId : CommandNotFoundException
In windows cmd: mydirectory>grep /? ‘grep’ is not recognized as an internal or external command, operable program or batch file.
In windows Powershell: PS mydirectory> grep /? The term ‘grep’ is not recognized as the name of a cmdlet, function, script file, or operable program. Check the spelling of the name, or if a path was included, verify that the path is correct and try again. At line:1 char:5
- I really found this article useful. Most new programmers might find reading the source code overwhelming, but this article may clear most of their doubts and make them understand that the strategies they used to read any book applies to reading source code as well. Thanks for this illustrative and creative article (which looks more attractive than formal neatly typed ones). Looking forward for more such articles.
Ur is a programming language, which among other things, has a rather interesting record system. Record systems are a topic of rather intense debate in the Haskell community, and I noticed that someone had remarked “[Ur/Web has a http://www.impredicative.com/ur/tutorial/tlc.html very advanced records system]. If someone could look at the UR implementation paper and attempt to distill a records explanation to a Haskell point of view that would be very helpful!” This post attempts to perform that distillation, based off my experiences interacting with the Ur record system and one of its primary reasons for existence: metaprogramming. (Minor nomenclature note: Ur is the base language, while Ur/Web is a specialization of the base language for web programming, that also happens to actually have a compiler. For the sake of technical precision, I will refer to the language as Ur throughout this article.)
In Haskell, if you want to define a record, you have to go and write out a
data declaration:In Ur, these two concepts are separate: you can define an algebraic data type (the
Foo constructor) and you can write types which describe a record (the { foo :: Int, bar :: Bool} bit of the type). To emphasize this point, there are actually a lot of ways I can spell this record in Ur/Web. I can define a type synonym:which offers me no protection from mixing it up with a structurally similar but semantically different
type qux = { Bar : int, Baz : bool }, or I can define:which desugars into:
that is to say, the datatype has a single constructor, which takes only one argument, which is a record! This definition is closer to the spirit of the original Haskell definition. (ML users might be familiar with this style; Ur definitely comes from that lineage.)
This design of separating algebraic data types from records means we now have obvious facilities for record construction (
let val x = { Bar = 2, Baz = true }) and record projection (x.Bar); though if I have a datatype I have to unwrap it before I can project from it. These record types are unique up to permutation (order doesn’t matter), which makes them a bit more interesting than HList. They are also nicely parsimonious: unit is just the empty record type {}, and tuples are just records with special field names: 1, 2, etc.Now, if this was all there was to the Ur record system, it wouldn’t be very interesting. But actually, the field
#Bar is a first class expression in the language, and the curly brace record type syntax is actually syntax sugar! Unpacking this will require us to define quite a few new kinds, as well as a lot of type level computation.In vanilla Haskell, we have only one kind:
*, which in Ur parlance is a Type. Values inhabit types which inhabit this kind. Ur’s record system, however, demands more exotic kinds: one such kind is the Name kind, which represents a record field name (#Foo is one). However, GHC has this already: it is the recently added Symbol kind. What GHC doesn’t have, however, is the kind constructor {k}, which is the kind of a “type-level record.” If value-level records are things that contain data, type-level records are the things that describe value-level records. They are not, however, the type of the value-level records (because if they were, their kind would be Type). Let’s look at a concrete example.When I write:
What I’m really writing is:
The
$ is a type level operator, being applied to the expression [ Bar = int, Baz = bool ], which is a type level record, specifically of kind {Type} (the “values” of the record are types). The dollar sign takes type level records, and transforms them into Type (so that they can actually be inhabited by values).This may seem like a meaningless distinction, until you realize that Ur has type level operators which work only on type level records, and not types in general. The two most important primitive type level operations are concatenation and map. They both do what you might expect: concatenation takes two records and puts them together, and map takes a type level function and applies it to every member of the record: so I can easily transform
[ Bar = int, Baz = bool ] into [ Bar = list int, Baz = list bool ] by mapping the list type constructor. Extensible records and metaprogramming dispatched in one swoop!Now, recall that field names all live in a global namespace. So what happens if I attempt to do
[ Bar = bool ] ++ [ Bar = int ]? The Ur type checker will reject this statement as ill-typed, because I have not provided the (unsatisfiable) proof obligation that these records are disjoint. In general, if I have two record types t1 and t2 which I would like to concatenate, I need a disjointness proof [t1 ~ t2]. Handling disjointness proofs feels rather unusual to users coming from traditional functional programming languages, but not all that odd for users of dependently typed languages. In fact, the Ur/Web compiler makes handling disjointness obligations very easy, automatically inferring them for you if possible and knowing some basic facts about about concatenate and map.The Ur record system crucially relies on type level computation for its expressiveness: we can expand, shrink and map over records, and we can also take advantage of “folders”, which are functions which use the type level records as structure to allow generic folding over records. For more information about these, I suggest consulting the type level computation tutorial. But in order to offer these features in a user friendly way, Ur crucially relies on a compiler which has some level of knowledge of how these operators work, in order to avoid making users discharge lots of trivial proof obligations.
Unfortunately, here I must admit ignorance as to how the rest of the Haskell record proposals work, as well as how a record system like this would interact with Haskell (Ur does have typeclasses, so this interaction is at least reasonably well studied.) While this proposal has the benefit of having a well specified system in an existing language, it is complex, and definitely shooting for the moon. But I think it says a bit about what might have to be added, beyond type-level strings, to fulfill Gershom Bazerman’s vision here:
It seems to me that there’s only one essential missing language feature, which is appropriately-kinded type-level strings (and, ideally, the ability to reflect these strings back down to the value level). Given that, template haskell, and the HList bag of tricks, I’m confident that a fair number of elegant records packages can be crafted. Based on that experience, we can then decide what syntactic sugar would be useful to elide the TH layer altogether.